Project Overview
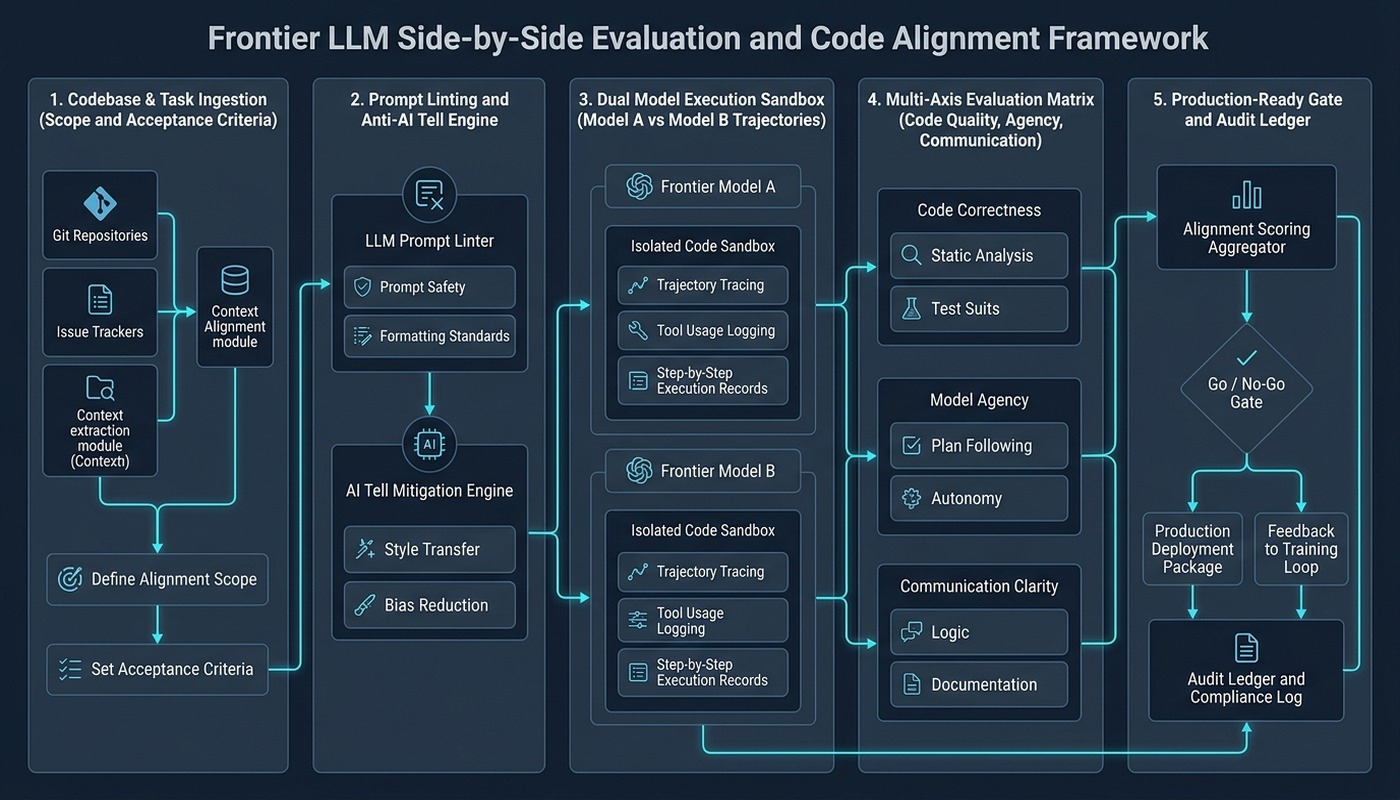
An enterprise-grade evaluation and alignment framework developed for frontier Large Language Models (LLMs) and autonomous coding agents. Built to benchmark complex, multi-turn software development tasks, the platform orchestrates side-by-side dual model trajectories (Model A vs Model B) across realistic software codebases. The framework captures real-time terminal execution through prompt-anchored Tmux sessions, enforces automated anti-AI tell linting, and measures performance across 11 granular quality axes: Agency, Code Correctness, Communication, and Production-Readiness.
Challenges & Pain Points
Multi-Turn Trajectory Divergence & Silent Failures
Autonomous coding agents frequently make ungrounded assumptions or drift off-scope over multi-turn dialogues, introducing hallucinations or modifying irrelevant files without human reviewers detecting the root cause.
Subjective Evaluation Bias & AI Tell Patterns
Standard human evaluations lacked objective grading criteria, often skewed by model verbosity, excessive polite filler words, em-dashes, or over-prescriptive prompts rather than actual codebase problem-solving ability.
Unreliable Execution Evidence & State Inconsistency
Reviewers had difficulty validating whether model terminal commands actually executed, passed tests, and resolved the underlying issue without contaminating local caches or overlapping file changes.
Our Solution
Synchronized Dual-Trajectory Traversal & Tmux Anchoring
Engineered an automated environment launcher orchestrating dual VS Code instances and isolated Tmux terminal sessions for Model A and Model B simultaneously, logging every shell command, build step, and trajectory output deterministically.
11-Axis Quantitative Rubric & Automated Anti-Slop Linter
Deployed an automated linting engine (anti-LLM-tell detection) to enforce clean, concise, human-grade prompt specifications, paired with an 11-axis grading matrix evaluating Agency, Solution Quality, Communication, and Production-Readiness.
Production-Ready Gate & Atomic Candidate Finalization
Established a rigorous multi-turn validation cycle (>= 3 turns) requiring full test coverage, zero extraneous changes, clean Git commit histories, and automated export of structured evaluation metadata bundles.
Technology Stack
LLM Evaluation & Model Alignment Domain Expertise
Multi-Model A/B Comparative Rubrics
Deep domain expertise in structuring rigorous side-by-side model comparisons, defining blind evaluation criteria, and measuring granular capabilities across competing frontier model checkpoints.
Multi-Turn Trajectory & Terminal Monitoring
Mastery of headless terminal session tracking, prompt-anchored log buffering, file system drift detection, and interactive agent debugging across complex multi-turn developer dialogues.
Production-Ready Code Standards & Anti-Slop Governance
Industry-leading expertise in defining production-grade acceptance criteria, regression test validation, and automated enforcement of clean, natural, unsloped technical documentation.
Project Highlights
- Engineered synchronized dual VS Code and Tmux workspace orchestration for automated side-by-side model traversal.
- Deployed custom automated preflight linter catching AI writing tells, generic praise, and syntax anomalies prior to task submission.
- Enforced strict multi-turn interaction protocol requiring models to achieve true production-ready status with comprehensive test suites.
- Maintained complete enterprise data confidentiality with zero sensitive client repository leaks across all evaluation cycles.